ClickHouse compression is a per-column decision with a measurable answer, and the measurement takes ten minutes. The default, LZ4 on every column, is a reasonable starting point and a poor finishing one: on a typical event table half the columns compress two to ten times better with a codec matched to their shape, and the bytes saved are bytes the query never reads from disk. This page is the eight codec choices we make on client schemas, the column shapes each one fits, the experiment that proves the choice on your own data, and the settings that govern compression cluster-wide.
The posts in this category explain the mechanics: how compression is implemented, the algorithms and codecs, the compress() function, time-series compression, and the column-store background. This page is the decision procedure that sits on top of them.
How ClickHouse compression is applied
Every column file in a part is a sequence of compressed blocks, each of up to max_compress_block_size bytes uncompressed, default 1 MiB, with a header naming the codec and a checksum. A codec is a pipeline: zero or more specialised transforms that reshape the bytes, followed by one general-purpose compressor. CODEC(Delta, ZSTD(3)) means delta-encode the values, then ZSTD the result; the general compressor is what produces the actual size reduction, and the transform is what makes the bytes compressible. The archive’s How data compression is implemented in ClickHouse walks through the block format.
Reads decompress whole blocks, so a query that needs one value from a granule decompresses the block that holds it. That is why compression ratio and decompression speed both matter, and why LZ4, which decompresses at several gigabytes per second per core, is the default: it costs almost nothing on the read path. ZSTD decompresses more slowly but compresses far better, and the trade-off is decided by whether the column is read hot or cold.
-- The compression map: where the bytes are, and how well each column compresses now
SELECT
    name,
    type,
    compression_codec,
    formatReadableSize(data_compressed_bytes)   AS compressed,
    formatReadableSize(data_uncompressed_bytes) AS uncompressed,
    round(data_uncompressed_bytes / greatest(data_compressed_bytes, 1), 1) AS ratio
FROM system.columns
WHERE database = 'analytics' AND table = 'events'
ORDER BY data_compressed_bytes DESC;
That query is the starting point of every ClickHouse compression review. The columns at the top are where the disk goes; the ones with a ratio under three are where the codec is wrong for the data.
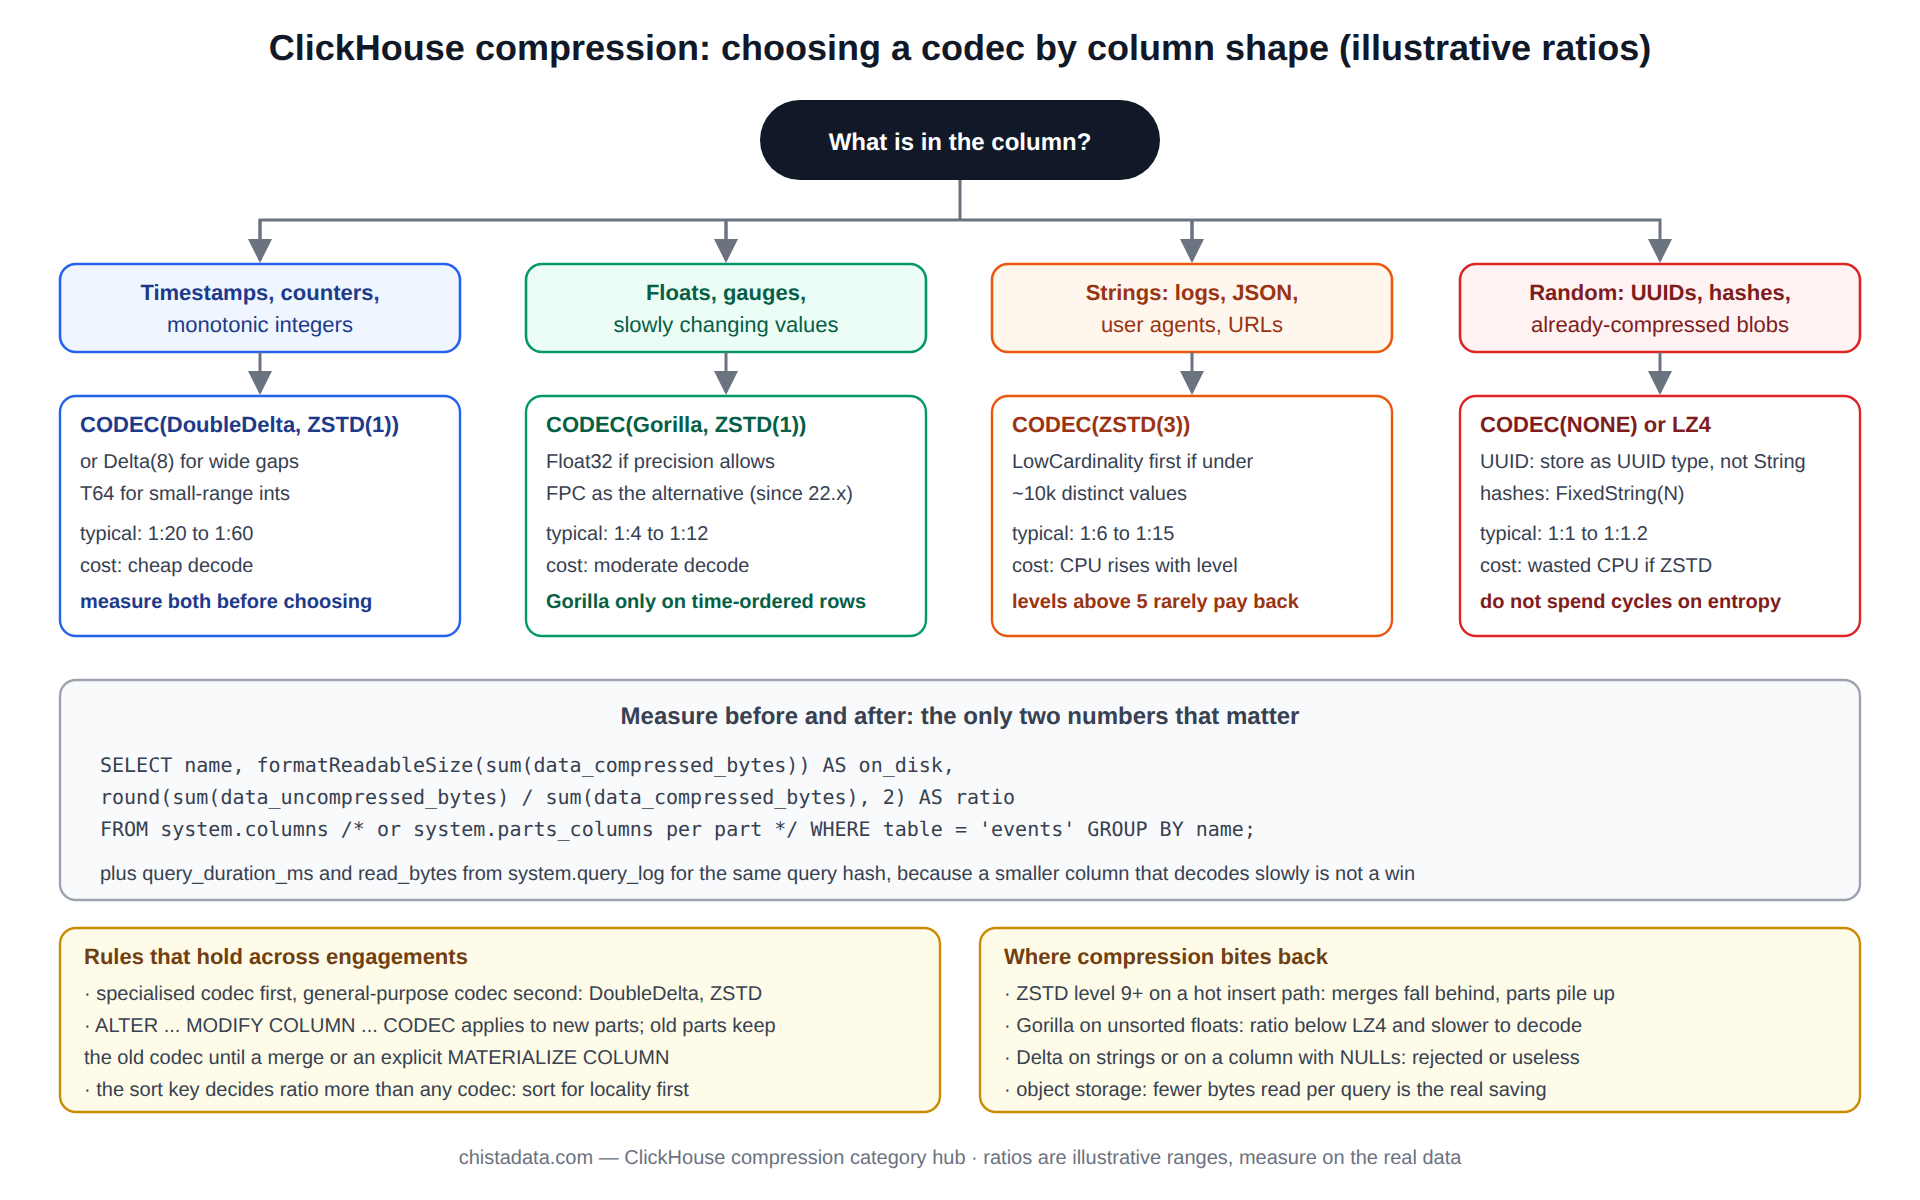
system.columns.ClickHouse compression choice one: timestamps and monotonic integers get Delta or DoubleDelta
A sorted DateTime or an auto-incrementing id changes by a small amount between consecutive rows. Delta stores the difference, which is small and repetitive; DoubleDelta stores the difference of the differences, which for regularly spaced timestamps is nearly always zero. Both followed by ZSTD routinely reach ratios of twenty to fifty on time columns that LZ4 alone leaves at four.
ALTER TABLE analytics.events
    MODIFY COLUMN event_time DateTime64(3, 'UTC') CODEC(DoubleDelta, ZSTD(1)),
    MODIFY COLUMN event_id   UInt64             CODEC(Delta, ZSTD(1));
The condition for this ClickHouse compression win is that the column is actually ordered within each part, which is true when it is in the sort key or correlated with it. A timestamp on a table sorted by tenant is ordered within each tenant’s run and still benefits; a random id gains nothing from Delta and can lose slightly. The archive post ClickHouse data compression for time-series data measures the family on a metrics table.
Choice two: floats get Gorilla or FPC, and only for slowly changing series
Gorilla XORs each float with the previous one and stores the changed bits, which works when consecutive values are close, as in a sensor reading or a price series. FPC, since 23.x, is a predictor-based float codec that often beats Gorilla on the same data. Neither helps on floats that jump, such as a latency column, where ZSTD alone is the answer. Test both; the difference between them is data-dependent and the test costs a minute.
ALTER TABLE metrics.readings
    MODIFY COLUMN value Float64 CODEC(Gorilla, ZSTD(1));
-- or
ALTER TABLE metrics.readings
    MODIFY COLUMN value Float64 CODEC(FPC, ZSTD(1));
Choice three: small integers and enums get T64
T64 works on integer columns whose values use far fewer bits than the type allows: a UInt32 holding status codes below 600, a UInt64 holding counts below a million. It transposes 64-value blocks and drops the unused high bits before the general compressor sees them. It is the codec for the wide integer column that should have been a narrower type and cannot be changed now.
Choice four: low-cardinality strings get LowCardinality first, then the codec
A String column with a few hundred distinct values is a type problem before it is a ClickHouse compression problem. LowCardinality(String) dictionary-encodes it into integer positions, which then compress with the ordinary codecs and, more importantly, are compared as integers at query time. Applying ZSTD to the plain String gives a good ratio and a slow query; converting the type gives both. The archive’s compression techniques in column-oriented databases post covers dictionary encoding as a class.
ALTER TABLE analytics.events MODIFY COLUMN event_type LowCardinality(String);
ALTER TABLE analytics.events MODIFY COLUMN country    LowCardinality(FixedString(2));
ClickHouse compression choice five: free text and JSON get ZSTD, level by temperature
Payloads, messages, user agents and serialised JSON have no shape a transform can exploit; they are the general compressor’s job alone. ZSTD(1) is the default level and is already far better than LZ4 on text. Levels three to six buy a further ten to twenty percent at increasing insert CPU; levels above nine are for cold data only, applied through a recompression TTL rather than at insert time. The archive post Compression algorithms and codecs in ClickHouse tabulates the levels.
ALTER TABLE analytics.events MODIFY COLUMN payload String CODEC(ZSTD(3));

-- Recompress parts older than 30 days at a higher level, in the background
ALTER TABLE analytics.events
    MODIFY TTL toDateTime(event_time) + INTERVAL 30 DAY RECOMPRESS CODEC(ZSTD(9));
Choice six: identifiers and hashes get ZSTD or nothing
UUIDs, random hashes and high-entropy tokens do not compress; they are random bytes by construction. ZSTD(1) recovers a little from any structure that exists, such as a shared prefix or a version nibble, and NONE is the honest choice when a test shows a ratio near one, because it saves the CPU. The one transform that helps is to store a UUID as the UUID type, sixteen bytes, rather than as its thirty-six-character string.
Choice seven: booleans and flags get the narrowest type and the default codec
A UInt8 flag column is already one byte per row and compresses to a few percent of that under LZ4 when the values run in streaks. There is nothing to gain from a specialised codec and something to lose in decompression time. The same is true of any column that is already tiny in the compression map; the review should spend its time on the top ten rows, not the bottom fifty.
ClickHouse compression choice eight: GCD and composed pipelines
GCD, since 23.x, divides integer values by their greatest common divisor, which turns a column of millisecond timestamps that are all whole seconds, or amounts that are all multiples of a hundred, into a smaller number space before Delta and ZSTD. Codecs compose left to right, and a pipeline of two transforms and a compressor is legal, for example CODEC(GCD, Delta, ZSTD(1)). Longer pipelines are rarely better and always slower; three stages is the practical limit.
| Column shape | Codec | Why | Typical ratio on real data |
|---|---|---|---|
| Timestamp, sorted | DoubleDelta, ZSTD(1) | regular spacing → near-zero second differences | 20–50× |
| Monotonic integer id | Delta, ZSTD(1) | small positive differences | 10–30× |
| Slowly changing float | Gorilla, ZSTD(1) or FPC, ZSTD(1) | XOR of neighbours is mostly zero bits | 5–15× |
| Small integers in wide types | T64, ZSTD(1) | drops unused high bits | 5–20× |
| Low-cardinality string | LowCardinality(String) + default | dictionary positions, integer compares | 10–100× |
| Free text, JSON | ZSTD(3), recompress to ZSTD(9) cold | general compressor only | 3–8× |
| UUID, hash | UUID type, ZSTD(1) or NONE | no structure to exploit | 1–1.5× |
| Flag, boolean | default LZ4 | already tiny | 10–50× |
The ratios in the table are illustrative ranges from client schemas, not a benchmark; the only number that matters is the one your own data produces in the experiment below.
What ClickHouse compression does to query speed
The reason to care beyond disk cost is the read path. A query reads compressed blocks from disk or page cache and decompresses them into memory; halving the compressed size halves the bytes read, and on a cold cluster that is close to halving the query time for a scan-bound query. The cost is decompression CPU, which for LZ4 is negligible and for ZSTD is small but measurable on the hottest columns.
The practical rule is LZ4 or ZSTD(1) on columns that appear in WHERE and GROUP BY of interactive queries, ZSTD(3) and up on payload columns that are read rarely, and the recompression TTL to move everything to a higher level once it is cold.
The measurement is the same four numbers from system.query_log that every performance change is judged by: read_bytes falls with the ratio, query_duration_ms falls with it on cold reads and holds steady on warm ones, and ProfileEvents['CompressedReadBufferBytes'] against ProfileEvents['CompressedReadBufferBlocks'] gives the effective block size the query saw. The archive post ClickHouse ETL optimization for high-velocity data measures the insert-side cost of ZSTD levels, which is the other half of the trade.
SELECT
    query_duration_ms,
    formatReadableSize(read_bytes)                                   AS read,
    ProfileEvents['CompressedReadBufferBlocks']                      AS blocks,
    formatReadableSize(ProfileEvents['CompressedReadBufferBytes'])   AS compressed_read
FROM system.query_log
WHERE type = 'QueryFinish' AND query_id = '${QUERY_ID}';
The ten-minute ClickHouse compression experiment
The procedure is the same for every column. Create a scratch table with the candidate codecs as separate columns, insert a representative sample of a few million rows from the real table, force a merge so the parts are final, and read the ratio per column from system.columns. The result is a table of ratios for the same data under each codec, and the decision is read directly from it.
CREATE TABLE scratch.codec_test
(
    ts_lz4     DateTime64(3, 'UTC') CODEC(LZ4),
    ts_delta   DateTime64(3, 'UTC') CODEC(Delta, ZSTD(1)),
    ts_ddelta  DateTime64(3, 'UTC') CODEC(DoubleDelta, ZSTD(1)),
    val_lz4    Float64 CODEC(LZ4),
    val_zstd   Float64 CODEC(ZSTD(1)),
    val_gor    Float64 CODEC(Gorilla, ZSTD(1)),
    val_fpc    Float64 CODEC(FPC, ZSTD(1)),
    txt_lz4    String  CODEC(LZ4),
    txt_zstd1  String  CODEC(ZSTD(1)),
    txt_zstd3  String  CODEC(ZSTD(3))
)
ENGINE = MergeTree ORDER BY ts_lz4;

INSERT INTO scratch.codec_test
SELECT event_time, event_time, event_time,
       latency_ms, latency_ms, latency_ms, latency_ms,
       payload, payload, payload
FROM analytics.events
WHERE event_time >= now() - INTERVAL 1 DAY
LIMIT 5000000;

OPTIMIZE TABLE scratch.codec_test FINAL;

SELECT name, compression_codec,
       formatReadableSize(data_compressed_bytes) AS compressed,
       round(data_uncompressed_bytes / data_compressed_bytes, 1) AS ratio
FROM system.columns
WHERE database = 'scratch' AND table = 'codec_test'
ORDER BY name;
Two refinements make the ClickHouse compression experiment honest. Sample from a full day rather than the last hour so that the daily cycle is represented, and insert in the real table’s sort order, because Delta and Gorilla depend on it. The compress() function, covered in the archive’s compress function post, is the quick alternative for a single column when a scratch table is too much ceremony.
Applying a ClickHouse compression change safely
ALTER TABLE ... MODIFY COLUMN ... CODEC is a metadata change: existing parts keep their old codec and new parts use the new one, and the old parts convert as they are merged. That makes the change reversible and cheap, and it also means the compression map does not show the full effect until the table has merged through, which on a large table can be weeks. To force it, ALTER TABLE ... MATERIALIZE COLUMN rewrites the column in every part as a mutation, which costs a full rewrite of that column and should be scheduled like any other mutation.
-- Metadata only; new parts use the new codec
ALTER TABLE analytics.events MODIFY COLUMN event_time DateTime64(3, 'UTC') CODEC(DoubleDelta, ZSTD(1));

-- Verify the change landed in the schema
SELECT name, compression_codec FROM system.columns
WHERE database = 'analytics' AND table = 'events' AND name = 'event_time';

-- Optional: rewrite existing parts now, as a tracked mutation
ALTER TABLE analytics.events MATERIALIZE COLUMN event_time;
SELECT mutation_id, parts_to_do, is_done FROM system.mutations WHERE table = 'events' ORDER BY create_time DESC LIMIT 1;
Rollback is the same statement with the previous codec. The blast radius is the mutation’s disk and CPU cost on a live table, so it runs in a quiet window with the merge pool watched, and on a replicated table it is issued once and replicates.
Settings that govern ClickHouse compression cluster-wide
Three server settings and two MergeTree settings shape the defaults. In config.xml, the compression section sets the default method per part-size band, which is how a cluster moves its default from LZ4 to ZSTD for large parts without touching any table. max_compress_block_size and min_compress_block_size, per query or profile, set the block size; larger blocks compress better and cost more per point read. network_compression_method and network_zstd_compression_level govern the wire, not the disk, and matter on cross-region replication. Server settings need a config reload; the block-size settings apply to new inserts.
<clickhouse>
  <compression>
    <case>
      <min_part_size>10000000000</min_part_size>
      <min_part_size_ratio>0.01</min_part_size_ratio>
      <method>zstd</method>
      <level>1</level>
    </case>
  </compression>
</clickhouse>
Object storage changes the ClickHouse compression arithmetic
On S3-backed tiers the bytes saved are billed twice: once as stored capacity and once as request traffic on every read. That shifts the balance toward higher ZSTD levels for anything that lives on the cold tier, applied through the recompression TTL at the same boundary as the TO VOLUME move, so that data is recompressed once as it leaves NVMe rather than in place on the object store.
The filesystem cache then holds the higher-ratio blocks, which means more of the hot working set fits in the same local cache. The ClickHouse partition hub covers the tiering rules; the compression rule is that the cold codec is chosen for ratio and the hot codec for decompression speed.
Version notes
FPC and GCD are 23.x and later. ZSTD_QAT, hardware-accelerated ZSTD on Intel QAT, appeared in 24.x and requires the accelerator. TTL ... RECOMPRESS is 20.x and later. DoubleDelta on DateTime64 requires the sub-second precision to be regular to pay off. The ClickHouse column compression codec documentation is the reference; confirm the running version before using a codec that arrived in a recent release.
Reading the archive
Start with Demystifying data compression in ClickHouse for the mechanism, then the codecs post and the time-series post for the family choices. The 26.8 LTS performance audit post lists the compression checks we run inside a wider review, and the ClickHouse performance IO hub explains why bytes saved on disk are the most direct read-performance lever there is.
A schema review that ends with ten codec changes is normal; one that ends with none usually means the table was designed by someone who had read this page. The compression map is worth re-running quarterly, because the column that was tiny at design time is often the one that a new feature turned into the largest on the table.
ChistaDATA’s ClickHouse consulting practice runs the compression review as a fixed-scope engagement with the experiment above executed on the client’s own data, and 24×7 ClickHouse support covers the mutations that follow. Run the experiment on staging with a real sample, apply codec changes one column at a time on production, and keep the previous codec recorded so that rollback is one statement.
